Common About Us paths include /about, /about-us, /company/about, and /our-story. These are useful candidates, but there is no universal path: find the link on the website before assuming a URL exists.
Here are some of the most common URL structures used for "About Us" pages:
- /about
- /about-us
- /about_me (for personal sites or blogs)
- /aboutus
- /company/about
- /company
- /our-story
- /our-company
- /who-we-are
- /meet-the-team
- /about-our-company
- /about-company
- /aboutus.html
- /about/index.html
Start with the site's navigation or footer and follow the actual About link. A site may use a different language, a custom path, or no About page at all. Guessing a path can return a 404 or an unrelated page.
How to follow About Us pages when scraping
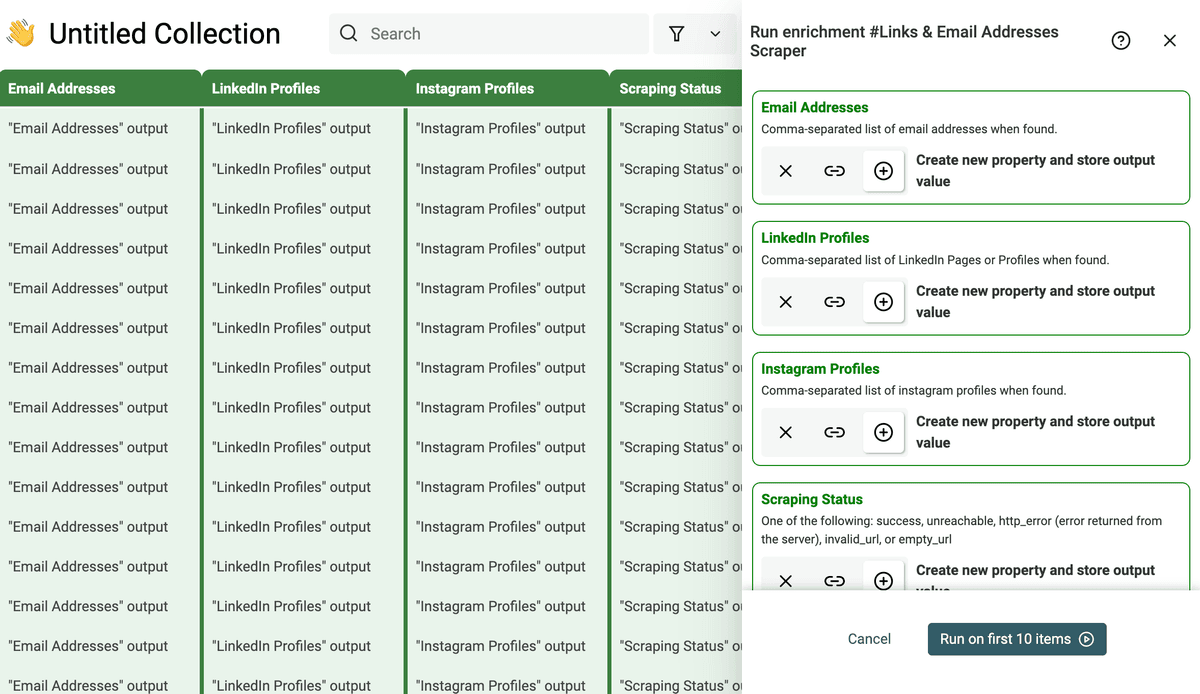
Import your website URLs into Datablist and select Smart Scraper. In the enrichment settings, enable Follow "About us" page. The scraper scans each supplied page for an About link and, when it finds one, follows it to extract available data. You do not need to build guessed URLs from the list above.
The best examples of data to extract are:
- Email addresses
- LinkedIn Company pages
- LinkedIn People profiles
- Phone numbers
- Social Links (Instagram, Facebook, Youtube, etc.)
- Texts that describe what a company does
An About page may provide these details, but the scraper can only return information present on pages it can access. Check the result before using a missing field as evidence that the company has no such information.